Use this 30-question RAG evaluation dataset template to check whether your retriever finds the evidence an answer needs. It includes a fictional source corpus, expected answers, stable question IDs, and a copyable CSV so you can run the exercise before adapting it to your own documents.
Editorial update: October 27, 2026. Added a complete fictional corpus and answer key, aligned IDs across examples, clarified retrieval metrics, and removed repeated text.

The demo works. The chatbot answers three happy-path questions. Everyone agrees the retrieval looks reasonable. Then a real user asks about an old policy, a product code, a refund exception, a versioned document, or a question the knowledge base cannot answer.
That is when the system starts sounding confident and wrong.
The fix is not a bigger model or a better prompt. The fix is a small, boring, repeatable evaluation set.
This guide gives you a practical RAG evaluation dataset template you can copy into a spreadsheet, CSV file, or test harness. It is designed to answer one question:
Can your retrieval system consistently find the right evidence before the LLM tries to answer?
The Short Version
Use a 30-question evaluation set before you tune prompts.
Your dataset should include:
- Straightforward answerable questions
- Questions with exact identifiers, SKUs, error codes, dates, and names
- Questions where the correct answer exists but is buried below similar chunks
- Questions with outdated or superseded documents
- Questions that should not be answered because the corpus does not contain the answer
- Questions that require two pieces of evidence
Track retrieval quality separately from answer quality. If the correct chunk never appears, the model is guessing.
What to record for each question
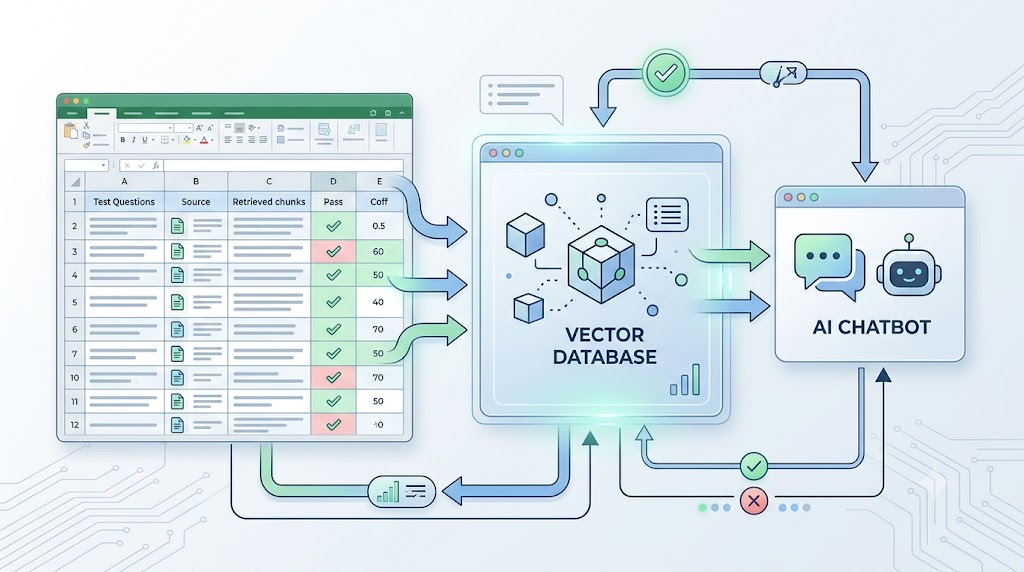
Keep the question ID, expected answer, relevant source IDs, answerability label, retrieved source IDs in rank order, generated answer, and review notes. Label the evidence before running retrieval so the output cannot influence your answer key.
The 30 Questions Your Dataset Should Include
Here is a balanced 30-question RAG evaluation dataset template structure that works for most product docs, policy libraries, support knowledge bases, internal wikis, and developer documentation.
| Group | Count | What it tests |
|---|---|---|
| Simple factual lookups | 5 | Whether normal retrieval works at all |
| Exact identifiers | 5 | Error codes, SKUs, ticket IDs, product names, API fields |
| Versioned or date-sensitive facts | 4 | Whether old documents outrank current ones |
| Similar concepts | 4 | Whether semantically close but wrong chunks confuse retrieval |
| Multi-hop questions | 4 | Whether the answer needs evidence from two places |
| Negative or exception cases | 3 | Whether policy exceptions are retrievable |
| Unanswerable questions | 3 | Whether the model refuses when evidence is missing |
| Duplicate/noisy document cases | 2 | Whether repeated chunks crowd out useful evidence |
That gives you enough coverage to find real problems without turning evaluation into a separate engineering project.
Fictional source corpus for this exercise
The policies, products, identifiers, and answers below are invented teaching data. They do not describe a real service. Save each passage under its displayed filename, then index those files in your retriever. The three unanswerable questions deliberately concern facts absent from this corpus. No retrieval experiment or measured result is claimed.
billing-policy-v2.md
SUPERSEDED by billing-policy-v3.md. Historical policy: monthly and annual subscriptions had a 14-day refund window from purchase.billing-policy-v3.md
CURRENT, effective 2026-01-01. Monthly subscriptions: refunds within 14 days from purchase. Annual subscriptions: refunds within 30 days from purchase. This replaces v2, which allowed 14 days for annual subscriptions.payments-errors.md
PX-104 means payment token expired. Refresh the payment token and retry once. AUTH-209 means an API token lacks the required scope. Ask an admin to issue a token with the required scope.api-reference.md
customer_status is the account state: trial, active, or suspended. Bulk user creation uses POST /users/bulk and is limited to 100 requests per minute per organization. Audit log export requires an API token with audit:read scope; role permissions are defined in enterprise-admin-guide.md.plans.md
Trial has no API access. Standard and Enterprise paid plans have API access. SSO and SCIM provisioning are Enterprise features. Maximum attachment size is 25 MB on Standard and 100 MB on Enterprise.support-sla-2026.md
Standard support: next business day first response. Premium support: 4-hour first response. These are first-response commitments, not resolution times.enterprise-admin-guide.md
Admins may export audit logs as CSV; viewers may not. API export also requires the scope listed in api-reference.md. Audit logs are retained for 90 days. Admins may restore deleted projects within 7 days; after that they cannot be restored.regions.md
Supported data-residency regions: United States, European Union, and India. Enterprise organizations may select India when the organization is created.import-guide.md
Import jobs skip rows whose external_id already exists. In the job result, the job owner or an admin may download skipped.csv containing skipped rows. Other users may not download it.The 30-question set and answer key
Use these IDs in both your evaluation log and CSV. For questions with multiple sources, retrieve all required evidence. A correct response to an unanswerable question states that the documents do not establish an answer.
| ID | Question | Expected answer | Source document(s) | Answerable? | Failure type |
|---|---|---|---|---|---|
| RAG-001 | What is the refund window for monthly subscriptions? | 14 days from purchase | billing-policy-v3.md | Yes | Direct lookup |
| RAG-002 | What is the refund window for annual subscriptions? | 30 days from purchase | billing-policy-v3.md | Yes | Similar policy confusion |
| RAG-003 | What happens after error code PX-104? | Payment token expired; refresh the token and retry once | payments-errors.md | Yes | Identifier search |
| RAG-004 | What does API field customer_status mean? | Account state: trial, active, or suspended | api-reference.md | Yes | Exact field lookup |
| RAG-005 | Which plan includes SSO? | Enterprise | plans.md | Yes | Product tier lookup |
| RAG-006 | Which plan includes SCIM provisioning? | Enterprise | plans.md | Yes | Similar feature confusion |
| RAG-007 | What is the SLA for standard support? | Next business day first response | support-sla-2026.md | Yes | Versioned fact |
| RAG-008 | What is the SLA for premium support? | 4-hour first response | support-sla-2026.md | Yes | Superseded document risk |
| RAG-009 | Can admins export audit logs? | Yes; admins can export CSV | enterprise-admin-guide.md | Yes | Permission lookup |
| RAG-010 | Can viewers export audit logs? | No; viewers cannot export audit logs | enterprise-admin-guide.md | Yes | Role exception |
| RAG-011 | How long are audit logs retained? | 90 days | enterprise-admin-guide.md | Yes | Date or retention fact |
| RAG-012 | Can deleted projects be restored? | Yes; admins can restore within 7 days | enterprise-admin-guide.md | Yes | Exception handling |
| RAG-013 | How long after deletion can a project be restored? | 7 days | enterprise-admin-guide.md | Yes | Time window |
| RAG-014 | Does the API allow bulk user creation? | Yes; POST /users/bulk | api-reference.md | Yes | API capability |
| RAG-015 | What rate limit applies to bulk user creation? | 100 requests per minute per organization | api-reference.md | Yes | API limit |
| RAG-016 | What authentication method is required for audit log export? | Admin role and an API token with audit:read scope | enterprise-admin-guide.md;api-reference.md | Yes | Multi-hop |
| RAG-017 | Can trial users access the API? | No; API access requires a paid plan | plans.md | Yes | Plan limitation |
| RAG-018 | What is the maximum attachment size? | 25 MB on Standard and 100 MB on Enterprise | plans.md | Yes | Numeric fact |
| RAG-019 | Does attachment size differ by plan? | Yes; Standard 25 MB and Enterprise 100 MB | plans.md | Yes | Similar facts |
| RAG-020 | Which regions support data residency? | United States, European Union, and India | regions.md | Yes | List retrieval |
| RAG-021 | Can users choose India data residency? | Yes; Enterprise organizations may choose India at creation | regions.md | Yes | Regional exception |
| RAG-022 | Is HIPAA supported? | Not stated in corpus | None | No | Unanswerable |
| RAG-023 | Is FedRAMP supported? | Not stated in corpus | None | No | Unanswerable |
| RAG-024 | Can invoices be paid in cryptocurrency? | Not stated in corpus | None | No | Unanswerable |
| RAG-025 | What changed in the 2026 billing policy? | Annual refund window increased from 14 to 30 days | billing-policy-v2.md;billing-policy-v3.md | Yes | Version comparison |
| RAG-026 | Which billing policy is current? | billing-policy-v3.md; v2 is superseded | billing-policy-v3.md | Yes | Superseded document risk |
| RAG-027 | What does error code AUTH-209 mean? | API token lacks the required scope | payments-errors.md | Yes | Identifier search |
| RAG-028 | What should a user do after AUTH-209? | Have an admin issue a token with the required scope | payments-errors.md | Yes | Procedure lookup |
| RAG-029 | Why did the import job skip duplicate rows? | Rows with an existing external_id are skipped | import-guide.md | Yes | Troubleshooting |
| RAG-030 | How can skipped duplicate rows be downloaded? | Open the job result and download skipped.csv; requires the job owner or an admin | import-guide.md | Yes | Multi-hop troubleshooting |
The exact questions matter less than the mix. If all your test questions are easy, your evaluation will say the system is good right until users prove otherwise.
Run the exercise
- Save and index the nine source files above. Keep the superseded billing policy so you can test version handling.
- Run each question through the same retriever configuration and save the top five results, source IDs, and generated answer.
- Compare the results with the answer key. Check role restrictions and time windows explicitly.
- Change one component, such as chunk size or reranking, and repeat the run. Record both improvements and regressions.
The set is a teaching fixture, not evidence of production accuracy. Add realistic user questions and a separate held-out set before using scores to make release decisions.
How to Score Retrieval
Start with retrieval before judging the final LLM answer. The RAG evaluation dataset template is most useful when retrieval and answer quality are scored separately.

Track these columns:
| Metric | What it means | Why it matters |
|---|---|---|
| Evidence Recall@5 | Number of required relevant sources found in the top 5 divided by the number of required relevant sources | Basic evidence availability |
| Correct chunk rank | Was the right chunk ranked 1, 2, 3, 4, or 5? | A larger numerical rank means relevant evidence is farther down the result list |
| No-answer accuracy | Did the system refuse unanswerable questions? | Prevents confident hallucination |
| Duplicate crowding | Did near-duplicate chunks fill the top results? | Reduces evidence diversity |
| Superseded hit rate | Did old documents outrank current ones? | Common source of wrong answers |
For example, RAG-016 requires both the admin guide and API reference. Retrieving only one gives source-level Recall@5 of 1/2 = 0.5. For a single-source question, finding that source gives 1.0. Average only over answerable questions. Hit@5 is a different measure: it records whether at least one relevant source was found.
The following optional 0–3 rubric is a custom review score; it is not Recall@5. Keep refusal accuracy separate from retrieval recall:
| Result | Score |
|---|---|
| Correct chunk ranked #1 | 3 |
| Correct chunk ranked #2-5 | 2 |
| Correct chunk retrieved below #5 | 1 |
| Correct chunk not retrieved | 0 |
| Unanswerable question correctly refused | 3 |
| Unanswerable question answered confidently | 0 |
You do not need a perfect metric on day one. You need a repeatable measurement that gets worse when retrieval gets worse and better when retrieval gets better.
How to Score the Final Answer
After retrieval, score the generated answer.
Use four labels:
| Label | Meaning |
|---|---|
| Correct | The answer is supported by retrieved evidence |
| Partially correct | The answer contains useful information but misses an important condition |
| Unsupported | The answer may be true, but the retrieved evidence does not prove it |
| Wrong | The answer contradicts the expected answer or source document |
Keep retrieval and answer scoring separate. A model can produce a correct answer from memory even when retrieval failed. That feels good in a demo, but it is not a reliable RAG system.
Failure Types to Label
Label each failed row with one main failure type.
| Failure type | What it usually means |
|---|---|
| No matching chunk | The source is missing, poorly chunked, or filtered out |
| Wrong similar chunk | Embeddings found a related topic but not the right fact |
| Identifier failure | Exact codes, names, or IDs were not handled well |
| Stale document | Old content outranked current content |
| Duplicate crowding | Near-duplicates filled the context window |
| Metadata filter error | Filtering removed the correct document |
| Unanswerable hallucination | The system answered without evidence |
| Synthesis failure | Retrieval worked, but the LLM combined evidence badly |
This is where the dataset becomes useful. A score tells you something is wrong. A failure label tells you what to fix.
How to interpret your results
There is no universal passing percentage for this fixture. Report counts alongside percentages: with only three unanswerable questions, one error changes refusal accuracy by about 33 percentage points. Review every failure and decide which risks are acceptable for your application. This article provides no measured benchmark or validated production threshold.
How to Build Your Own Dataset
Start with documents that users actually search.
Good sources:
- Support tickets
- Sales engineering questions
- Internal Slack or Teams questions
- Product documentation
- Policy documents
- API docs
- Incident postmortems
- Customer onboarding questions
For each question, record the source document before you run the test. If you do not know the expected source, you are not evaluating the system. You are exploring it.
A Practical CSV Version
Copy the complete CSV below into a UTF-8 file. Each record matches the question and answer key above. Fill retrieved_ids with semicolon-separated source IDs in retrieval order and answer_label with correct, partially correct, unsupported, or wrong.
"id","question","expected_answer","source_document","answerable","expected_failure_type","retrieved_ids","answer_label","notes"
"RAG-001","What is the refund window for monthly subscriptions?","14 days from purchase","billing-policy-v3.md","yes","Direct lookup","","",""
"RAG-002","What is the refund window for annual subscriptions?","30 days from purchase","billing-policy-v3.md","yes","Similar policy confusion","","",""
"RAG-003","What happens after error code PX-104?","Payment token expired; refresh the token and retry once","payments-errors.md","yes","Identifier search","","",""
"RAG-004","What does API field customer_status mean?","Account state: trial, active, or suspended","api-reference.md","yes","Exact field lookup","","",""
"RAG-005","Which plan includes SSO?","Enterprise","plans.md","yes","Product tier lookup","","",""
"RAG-006","Which plan includes SCIM provisioning?","Enterprise","plans.md","yes","Similar feature confusion","","",""
"RAG-007","What is the SLA for standard support?","Next business day first response","support-sla-2026.md","yes","Versioned fact","","",""
"RAG-008","What is the SLA for premium support?","4-hour first response","support-sla-2026.md","yes","Superseded document risk","","",""
"RAG-009","Can admins export audit logs?","Yes; admins can export CSV","enterprise-admin-guide.md","yes","Permission lookup","","",""
"RAG-010","Can viewers export audit logs?","No; viewers cannot export audit logs","enterprise-admin-guide.md","yes","Role exception","","",""
"RAG-011","How long are audit logs retained?","90 days","enterprise-admin-guide.md","yes","Date or retention fact","","",""
"RAG-012","Can deleted projects be restored?","Yes; admins can restore within 7 days","enterprise-admin-guide.md","yes","Exception handling","","",""
"RAG-013","How long after deletion can a project be restored?","7 days","enterprise-admin-guide.md","yes","Time window","","",""
"RAG-014","Does the API allow bulk user creation?","Yes; POST /users/bulk","api-reference.md","yes","API capability","","",""
"RAG-015","What rate limit applies to bulk user creation?","100 requests per minute per organization","api-reference.md","yes","API limit","","",""
"RAG-016","What authentication method is required for audit log export?","Admin role and an API token with audit:read scope","enterprise-admin-guide.md;api-reference.md","yes","Multi-hop","","",""
"RAG-017","Can trial users access the API?","No; API access requires a paid plan","plans.md","yes","Plan limitation","","",""
"RAG-018","What is the maximum attachment size?","25 MB on Standard and 100 MB on Enterprise","plans.md","yes","Numeric fact","","",""
"RAG-019","Does attachment size differ by plan?","Yes; Standard 25 MB and Enterprise 100 MB","plans.md","yes","Similar facts","","",""
"RAG-020","Which regions support data residency?","United States, European Union, and India","regions.md","yes","List retrieval","","",""
"RAG-021","Can users choose India data residency?","Yes; Enterprise organizations may choose India at creation","regions.md","yes","Regional exception","","",""
"RAG-022","Is HIPAA supported?","Not stated in corpus","","no","Unanswerable","","",""
"RAG-023","Is FedRAMP supported?","Not stated in corpus","","no","Unanswerable","","",""
"RAG-024","Can invoices be paid in cryptocurrency?","Not stated in corpus","","no","Unanswerable","","",""
"RAG-025","What changed in the 2026 billing policy?","Annual refund window increased from 14 to 30 days","billing-policy-v2.md;billing-policy-v3.md","yes","Version comparison","","",""
"RAG-026","Which billing policy is current?","billing-policy-v3.md; v2 is superseded","billing-policy-v3.md","yes","Superseded document risk","","",""
"RAG-027","What does error code AUTH-209 mean?","API token lacks the required scope","payments-errors.md","yes","Identifier search","","",""
"RAG-028","What should a user do after AUTH-209?","Have an admin issue a token with the required scope","payments-errors.md","yes","Procedure lookup","","",""
"RAG-029","Why did the import job skip duplicate rows?","Rows with an existing external_id are skipped","import-guide.md","yes","Troubleshooting","","",""
"RAG-030","How can skipped duplicate rows be downloaded?","Open the job result and download skipped.csv; requires the job owner or an admin","import-guide.md","yes","Multi-hop troubleshooting","","",""
What to Fix Based on the Result
If exact identifiers fail, add keyword or hybrid search. Dense embeddings alone often struggle with error codes, SKUs, table names, ticket IDs, and API fields.
If stale documents rank highly, add version metadata, freshness rules, document status fields, and filters that exclude superseded content by default.
If duplicate chunks crowd the top results, add deduplication after retrieval or diversify results by source document.
If the correct chunk appears at rank 4 or 5, improve reranking before changing the prompt.
If unanswerable questions get confident answers, add an evidence gate: the model should answer only when retrieved chunks contain enough support.
If retrieval works but answers are wrong, then inspect the prompt, context ordering, citation requirements, and synthesis step.
Maintain the dataset
Add a regression question whenever a real user exposes a retrieval failure. Update the answer key when source documents change, retain useful version-conflict cases, and keep a decision log explaining why rows were added or retired. Use a held-out set to check whether tuning on familiar examples generalizes.
Common Mistakes When Evaluating RAG
The most common mistake is testing only easy questions. Easy questions prove that the demo works, but they do not prove that retrieval is reliable. A strong dataset includes awkward questions, narrow exceptions, old policy names, exact error codes, and cases where the system should refuse to answer. These rows are more valuable than another generic question with an obvious answer.
Another mistake is scoring the final answer without looking at the retrieved chunks. If the model gives a correct answer from memory while retrieval failed, the system still has a retrieval problem. That answer may look fine today and fail tomorrow when the same pattern appears in a domain the model does not already know. Always inspect whether the correct evidence was actually present in the context.
Teams also forget to test unanswerable questions. This is risky because many hallucinations start when the retriever returns related but insufficient context. Add questions where the correct answer is not in the corpus, then check whether the assistant says that the evidence is missing. A RAG system that refuses unsupported questions is usually more useful than one that tries to answer everything.
Finally, avoid changing too many variables at once. If you change chunk size, embedding model, reranker, prompt, and metadata filters in the same experiment, you will not know what helped. Use the RAG evaluation dataset template to compare one change at a time. Keep the baseline score, run the new configuration, and record what improved or regressed.
Keep the RAG evaluation dataset template close to your release notes so every retrieval change has a clear before-and-after comparison.
A Simple Weekly RAG Evaluation Workflow
If your team wants a lightweight process, run the evaluation every week or before each major documentation release. Start by exporting the current dataset rows. Run each question through the same retrieval pipeline your application uses in production. Save the top retrieved chunks, their source documents, and their rank. Then score whether the expected evidence appeared before judging the final generated answer.
After scoring, group failures by type. If most failures are exact identifiers, add hybrid search or keyword matching. If stale documents keep winning, improve metadata and freshness filters. If correct chunks appear low in the list, test a reranker. If retrieval is strong but final answers are weak, then work on the answer prompt, citation rules, or response formatting.
The best workflow ends with a short decision log. Write down what changed, whether Recall@5 improved, whether no-answer accuracy improved, and which failure types remain. This history makes future SEO, product, and engineering work easier because you can explain why the system improved instead of relying on gut feeling.
When a 30-Question Dataset Is Not Enough
Thirty questions are enough to start, but mature systems usually need more coverage. Expand the dataset when the knowledge base has many product areas, when users ask questions in different languages, or when answers depend on customer plan, region, date, or role. These conditions create retrieval edge cases that a small dataset may miss.
A good next step is to grow from 30 rows to 100 rows. Keep the same structure, but add more examples for each failure type. Include duplicates, ambiguous wording, long questions, short keyword-style searches, and questions copied from real support tickets. The larger set should still be practical to run. If evaluation becomes too slow, teams stop using it.
For high-risk workflows, combine automated scoring with human review. Let automation flag likely failures, but ask a reviewer to inspect uncertain rows, policy-sensitive answers, and unsupported claims. This gives you speed without pretending that every judgment can be fully automated.
FAQ
How many questions do I need for RAG evaluation?
Start with 30 questions. That is enough to cover common failure modes without slowing the team down. Increase to 100 or more once the system supports real users or high-risk workflows.
Should I evaluate retrieval or the final answer?
Evaluate both, but keep the scores separate. Retrieval tells you whether the right evidence was available. Final-answer scoring tells you whether the LLM used that evidence correctly.
What is a good Recall@5 score for RAG?
Choose a target from your application risks and representative evaluation data. Report evidence coverage and failure counts; this small fictional exercise cannot establish a production threshold.
Should I use an LLM as a judge?
You can, but start with human-labeled expected answers. LLM judges are useful for scaling review, but they should be tested against human labels before you trust them.
Why include unanswerable questions?
Because users ask questions your corpus cannot answer. A RAG system that cannot say “I do not know from the provided documents” will eventually hallucinate.
What is the fastest way to improve a weak RAG system?
Look at the retrieved chunks before changing the prompt. If the correct evidence is missing, fix retrieval, chunking, metadata, reranking, or document quality first.
Where to Go Next
If your results show retrieval failures, read the GenAITrail guide on why RAG returns wrong answers. It walks through the most common failure modes in more detail, including score thresholds, identifiers, duplicate chunks, stale documents, and unanswerable queries.
If your retrieval is working but the generated answers are inconsistent, evaluate the answer step separately with an LLM-as-a-judge workflow and human-labeled examples. For a broader evaluation foundation, compare your process with the OpenAI Evals guide and the Google Cloud RAG architecture guide.
The goal is not to make your RAG system sound better. The goal is to make it easier to catch wrong answers before your users do.
